> ## Documentation Index
> Fetch the complete documentation index at: https://cortex-foundation-add13747-droid-2a5c5e50-docs-ferndesk-pro.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# Streaming
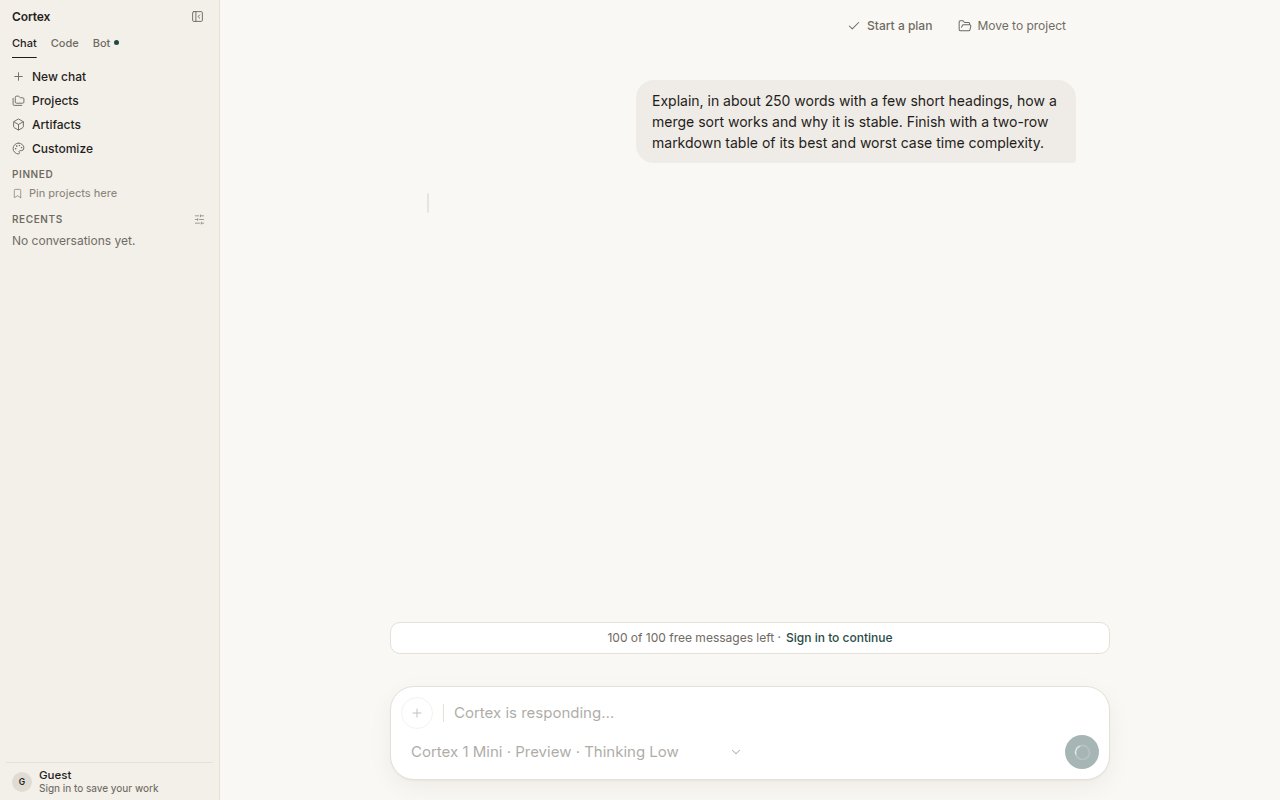
> Answers appear as they are written — tokens, then tools, then the finished reply. If the connection drops, the thread reconnects; you do not resend.
Chat streams. You see the answer being written rather than a block of text after the turn ends, and you can stop it at any point.
 ## What streams, in order
| Phase | What you see |
| -------- | ------------------------------------------------------------------------------------------ |
| Thinking | A blinking caret while the model reasons; longer at higher [thinking levels](/chat/models) |
| Tokens | The reply appearing word by word, markdown rendering as it lands |
| Tools | Tool results entering the thread when the model uses one |
| Finished | **Copy**, **Listen**, and feedback controls under the reply |
A turn can pass through the tool phase more than once. The model asks for a tool, Chat runs it, the result enters the thread, and the model keeps writing — until it stops or reaches Chat's round budget. That is the loop described in [How Chat works](/chat/how-it-works), and it is why a turn that uses a tool takes longer to look finished than one that does not.
A [Deep Research](/chat/deep-research) run streams differently: each planned question is a background child, so the thread fills from several sources at once rather than one reply growing word by word.
## Stop a response
Press **Esc**, or the stop control where the send button was. The partial reply stays in the thread. See [Keyboard shortcuts](/getting-started/settings#keyboard-shortcuts).
## When the connection drops
Run state lives in the thread, not in the transport. If your connection drops mid-reply, the product reconnects and the reply that already started continues. **Do not resend** the same message to recover it — you would start a second turn.
## Queueing
Sending while a reply is still streaming is not the intended path in the web app; wait for the reply or stop it first. The CLI queues follow-ups explicitly — see [The TUI](/cli/tui).
## Where the answer is written
Streaming is the transport, not the record. The thread holds the run state, which is why a dropped connection can resume the reply it already started and why a partial reply survives a stop. The same thread is what the [Library](/chat/library) fetch and the **Copy**, **Listen**, and feedback controls attach to when the reply finishes.
Long threads are compacted on the request path so they keep fitting the model. Compaction keeps the last ask, an active research plan, and open artifact ids — it does not keep every word you ever typed. See [How Chat works](/chat/how-it-works).
## Related
* [How Chat works](/chat/how-it-works) — the loop behind the stream.
* [Voice](/chat/voice) — **Listen** appears once the reply is finished.
* [Chat troubleshooting](/chat/troubleshooting) — a reply cut short, and what not to do about it.